Your Data Team Has 94 Ad-Hoc Requests Open and Analysts Shipped Eleven This Sprint
VP Data opens the Jira queue Monday, 94 ad-hoc requests open across go-to-market, finance, and product, 11 shipped this sprint, 68 aging past 21 days. A queue nobody staffed.
It is Monday, 8:52 AM. Your VP Data opens the Jira analytics queue before the exec sync. 94 ad-hoc requests sit open across go-to-market, finance, product, and the CEO's personal Slack thread. He sorts by created date. The top row reads 54 days, a CFO request for net revenue retention cut by cohort and plan tier, filed August 13th with four Slack nudges stacked on it. The next six rows read 41, 38, 33, 27, 24, 21. Sixty-eight requests in the queue are aging past 21 days.
He opens the sprint board. 11 tickets shipped last sprint across three analysts and one analytics engineer. Four were recurring exec-dashboard refreshes. Three were board-prep pulls the CFO flagged inside 72 hours. Two were growth-team funnel cuts the PMM lead paired on. Two were pricing-team cohort pulls the CRO escalated. The remaining 83 sat in the backlog with no owner, no SLA, and no routing rule off intent.
He opens Looker. 142 dashboards live. 61 flagged "last viewed over 60 days." The semantic layer in dbt holds 420 modeled tables, 180 of them untested. The data catalog in Atlan reads 1,100 columns documented, 2,400 undocumented. The warehouse spend ran $38K on Snowflake last month, 61 percent of query compute hitting four tables the growth team re-queries from Mode notebooks nobody shares.
Pull the quarter. 273 analytics requests filed across Q3, 94 open, 179 closed, 42 of the 179 closed inside a 48-hour SLA, 137 closed past day 14. The CRO flags four pipeline reviews running on stale cuts. The CFO flags two board slides built off a Mode query the analyst who wrote it left in February. The PMM lead flags three launch readouts shipped off a dashboard the growth lead rebuilt without telling anyone. The function nobody staffed is costing the business four exec decisions on stale data, nine launch readouts shipping late, and three Snowflake invoices nobody can explain.
Analytics request handling is a function. Most Series B and C teams staffed it with a lead data analyst who runs the exec cuts, two to four analysts who clear the sprint, an analytics engineer who owns dbt, and a VP Data who runs the Thursday priority call. The function lives in the gap between the lead who owns the roadmap, the analysts who own the queue, the analytics engineer who owns the semantic layer, and the business leaders who own the questions. On the org chart it reads Data. In practice it reads a shared Jira project nobody owns.
The 68-request backlog math
Pull every ad-hoc request filed in the last 180 days. Log the requester, the question, the filed date, the first-touch date, the first-answer date, the delivered date, and the handoff count. Count requests aging past 7 days without a first touch. Count requests pulled back by the requester as "never mind, I built it in a spreadsheet." Count duplicate requests covering the same question across different Slack channels. Most Series B teams past 150 employees find 55 to 70 percent of ad-hoc requests sitting past day 14, 25 to 40 percent withdrawn by the requester, and 15 to 30 percent duplicates nobody caught.
Walk one request. The August 13th CFO ticket asked for net revenue retention cut by cohort and plan tier against the Q2 budget. The lead analyst tagged it "needs dbt model" and dropped it in the backlog. The analytics engineer was shipping the pricing model the CRO flagged on the 10th. The second analyst was on the board-prep pull the CEO escalated. The third was on a growth-team funnel cut that pulled four days. The CFO request sat. The CFO pinged on the 20th. The lead flagged it for the next sprint. The next sprint was pricing. By September 10th the CFO had an intern pull it in a spreadsheet and the board slide shipped on numbers nobody at the data team reviewed.
The team that should own this knows it is broken. The lead analyst runs the Thursday priority call. The analysts carry 14 to 22 open tickets each. The analytics engineer runs dbt model requests off a separate GitHub queue nobody cross-checks against Jira. The VP Data runs skip-levels on Friday afternoons and reports sprint velocity in the Monday staff meeting. The 68-request backlog is the question nobody charged against a cadence.
Why Looker and dbt do not answer a question
You bought Looker or Metabase at $84K to $160K a year for the dashboarding layer. You bought dbt Cloud at $14K to $42K a year for the transformation layer. You bought Snowflake at $340K to $820K a year for the warehouse. Looker renders the chart off a modeled explore. dbt runs the sql that builds the explore. Snowflake stores the data and bills on compute. Neither reads the CFO's Slack question, writes the three-way-join scoped against the right cohort window, pulls the Q2 budget target from the finance workbook, and ships a 15-minute answer with the caveats named.
Looker reports the net-revenue-retention dashboard was opened 42 times in September. It does not know whether the CFO's question maps to the dashboard's grain. dbt ships the fact_subscription model nightly. It does not score whether the model matches the plan-tier cut the pricing team shipped in July. Snowflake bills $14K on query compute last month. It does not flag the 61 percent of compute hitting four tables that already have a cached answer in Mode. The storage layer is a storage layer. The transformation layer is a transformation layer. Neither is a function.
What a fractional AI analytics ops function does
Hand the Jira analytics queue, the dbt semantic layer, the Looker catalog, the Mode notebook archive, the finance workbook, the Slack history of past exec questions, the data dictionary, and the sprint roadmap to a fractional AI agent. The agent does the work a lead analyst, a junior analyst, and an analytics engineer would do together. The cadence is per-request on intent routing, per-day on the backlog digest, per-sprint on the roadmap sync, per-release on the semantic-layer refresh, and per-event on the exec question thread.
Every request routed inside 20 minutes. The CFO Slack question lands at 2:14 PM. By 2:34 the agent has scored the intent against the dbt catalog, flagged the three existing models that answer 80 percent of the ask, drafted the scoped sql, pulled the Q2 budget target from the finance workbook, and shipped a 15-minute answer with the two caveats on the cohort window named. The CFO reads the number in Slack and the lead analyst sees the full working.
Every ad-hoc request first-passed inside two hours. The CRO Monday pipeline-review question lands at 10:04 AM. By 11:50 the agent has pulled the opportunity-stage data, scored it against the Q3 cohort cut the pricing team filed in July, flagged the two deals the Salesforce stage data contradicts the Gong call signal on, and shipped a 15-minute readout with the two sources of truth named.
Every duplicate caught before it burns a sprint. The PMM lead files a launch readout request. The agent flags the growth-team ticket filed 11 days earlier covering the same event cut and the Mode notebook the growth analyst shipped on September 22nd. One ticket closes, one request routes to the existing notebook, one hour of analyst time saves on the swap.
Every Snowflake query re-scored on compute. The Monday warehouse digest lists the four tables burning 61 percent of compute, the 11 Mode notebooks hitting them, the three dbt models that could cache the answer, and the one Looker explore that already does. The analytics engineer runs the cache rebuild Tuesday and the invoice drops 14 to 22 percent inside the month.
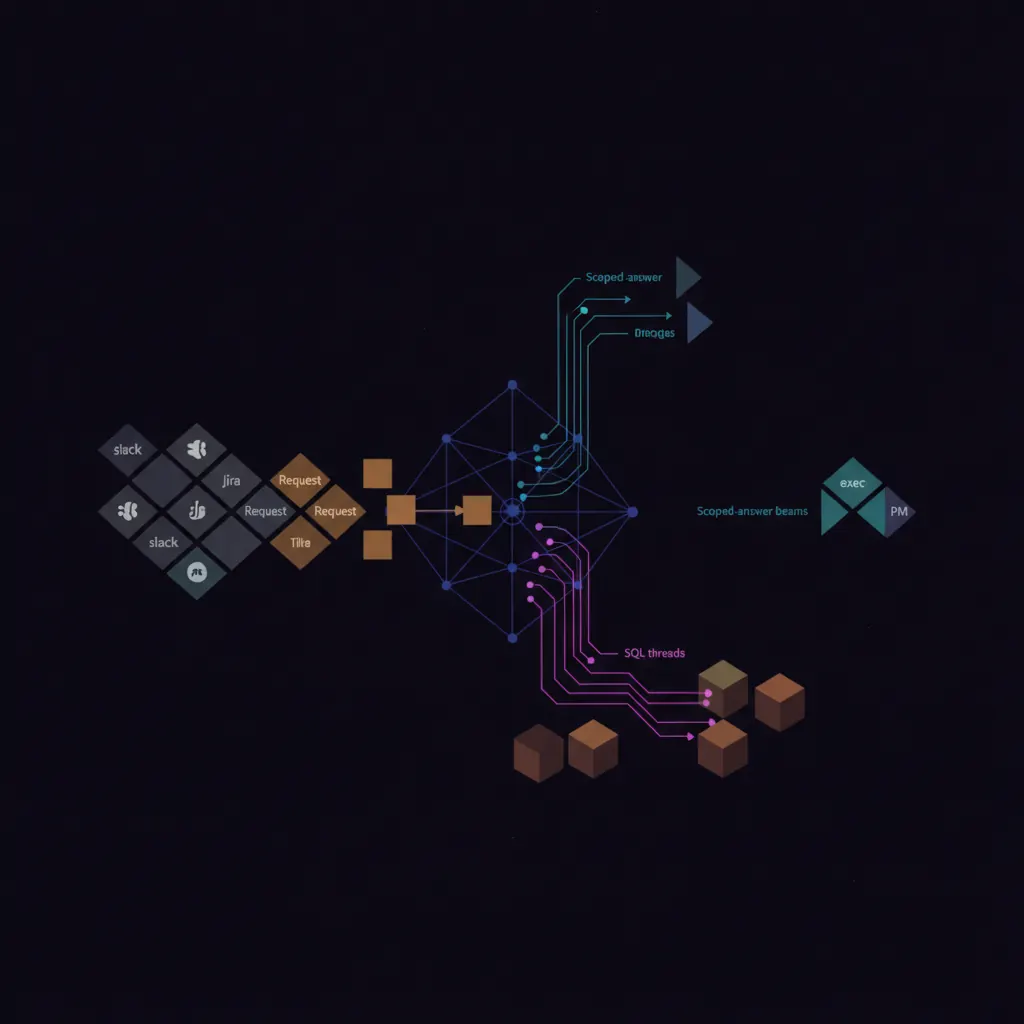
The unit economics of a 94-request queue
A Series B at $14M ARR running 273 analytics requests a quarter is burning three lines. The lead analyst, three analysts, and the analytics engineer clear 22 to 34 hours a week on first-touch triage, duplicate hunting, and backlog explaining against a loaded hour of $150 to $280. That is $14K to $38K a month of senior data time on questions a live agent clears to a 15-minute scoped answer. The analysts get nine to fourteen hours a week back on the modeling that compounds.
The decision line is the second. Pulling request cycle time from 23 days to 1 moves four to seven exec decisions a quarter off stale cuts. Board slides stop shipping on numbers nobody reviewed. Launch readouts land the day of the launch instead of the next sprint. Pricing calls run against the cohort cut the pricing team shipped last, not the one from April.
The warehouse line is the third. Catching 61 percent of compute hitting four re-queried tables and routing the Mode notebooks to a cached dbt model drops the Snowflake invoice 14 to 22 percent on a $38K monthly run. On a full year that is $64K to $100K the warehouse stops billing against questions already answered.
A 14-day sprint to stand up the agent runs in the low to mid five figures. Ongoing cost lands at $4K to $9K a month on API spend, warehouse read access, and tooling plus a fractional analytics operator at $5K to $9K a month who owns the Thursday priority call and the backlog review. Intent routing and scoped answers ship in week one. Duplicate detection and the warehouse digest ship in week two. The 68-request backlog clears inside the sprint.
What changes after the sprint
Picture the same Monday, 8:52 AM moment, thirty days after the sprint ships. Your VP Data opens the Jira queue. 11 requests open. The oldest reads 3 days, a product-team funnel question that landed Thursday with the scoped sql already attached. The ad-hoc queue reads six, all tagged with the dbt model that answers them. The CFO reads a Slack thread where the net-retention cut landed inside 22 minutes of the question, with the two cohort caveats named in line.
By Thursday the VP Data reads a backlog digest that names the three requests over 14 days, the modeling blocker on each, and the analyst who owns the next step. The CFO reads a weekly data digest that names the five numbers moving against plan with the dbt model and the finance workbook row for each. The pricing team runs cohort cuts against the current semantic layer instead of a Mode notebook from April. The analytics engineer stops firefighting duplicate requests and ships the three dbt models the roadmap flagged in July.
If your Jira queue currently reads 94 requests open with 68 aging past 21 days, the version where every exec question clears inside 20 minutes and every duplicate catches before it burns a sprint is fourteen days away. Analytics request handling is a function. You can hire a staff analyst against it, you can expand the fractional analytics retainer, or you can scope a sprint and have it running this month. The work is the same. The backlog is not.
- 2026-10-05
How SeoulClinics Leverages AI in Medical Tourism in 2026
SeoulClinics replaces the broker middleman with an AI directory that matches foreign patients to Korean clinics in two languages. Here is the operating shape.
- 2026-10-05
How Polyclaw Leverages AI in Prediction Market Trading in 2026
Polyclaw runs a multi-tenant Polymarket trading bot that gives retail traders institutional-grade signals. Here is how the SaaS layer unseats hedge-fund infra.
 2026-09-29
Your AR Aging Has 47 Invoices Past 60 Days and Finance Chased Six
Your CFO opens the aging report Monday, 47 invoices past 60 days in Q3, six live collections threads, 41 stale reminders sitting in a Netsuite view. A queue nobody staffed.